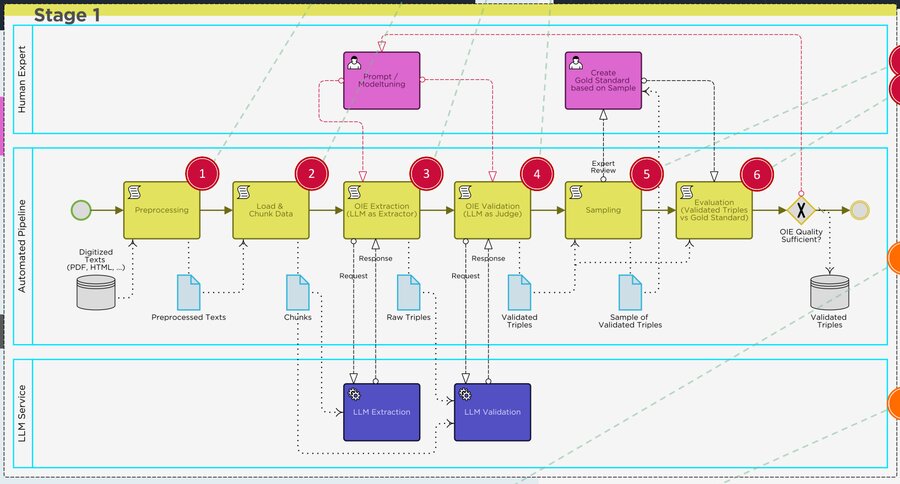
Extracting structured knowledge graphs from unstructured historical texts is precise but slow when done by hand, and hard to automate without losing the nuances of historical sources. This chapter presents a two-stage computational pipeline — open information extraction followed by LLM-based validation — built to connect large, previously isolated sources like biographical lexicons into usable knowledge graphs.
Read the paper
- Authors: Raphael Schlattmann, Aleksandra Kaye, and Malte Vogl
- In: Understanding Science with Large Language Models? Potentials for the History, Philosophy, and Sociology of Science, ed. Arno Simons, Adrian Wüthrich, Michael Zichert, and Gerd Graßhoff (transcript, 2026), pp. 307–334
- DOI: 10.14361/9783839447529-307
- Featured image: detail from the accompanying poster Silo to Structure (Stage 1 of the extraction pipeline)